Seven experiments to explore AI tools and review their results.
01What can we learn from 300 synthetic records?My first AI and Google Colab analysis practice: calculating, interpreting and checking results.Synthetic dataOpen practiceClose practice
Synthetic data
Context
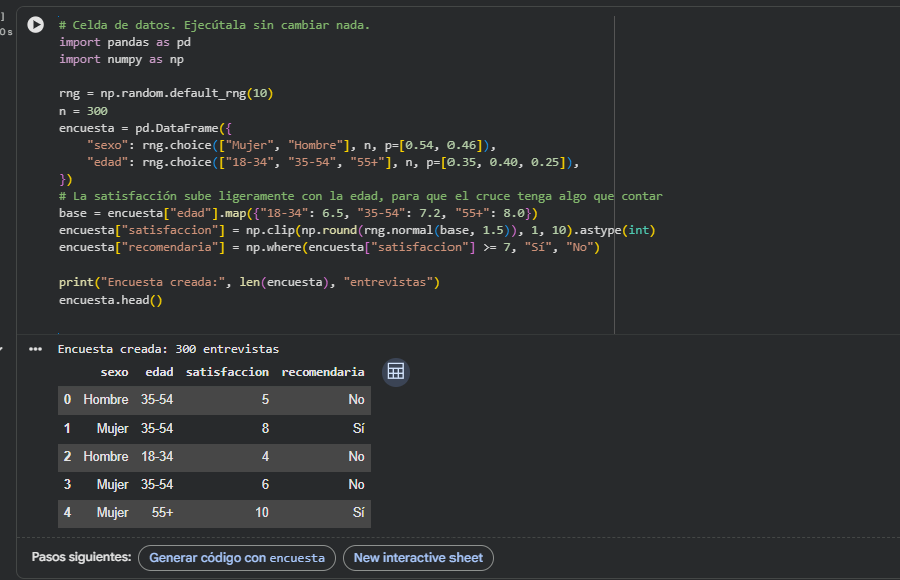
A learning exercise using 300 synthetic records generated by code supplied in the course: Curso Práctico de Inmersión en la IA para Investigadores de Mercados, 10.ª edición, de Insights + Analytics España. This page documents Exercises 3 and 4.
What I wanted to find out
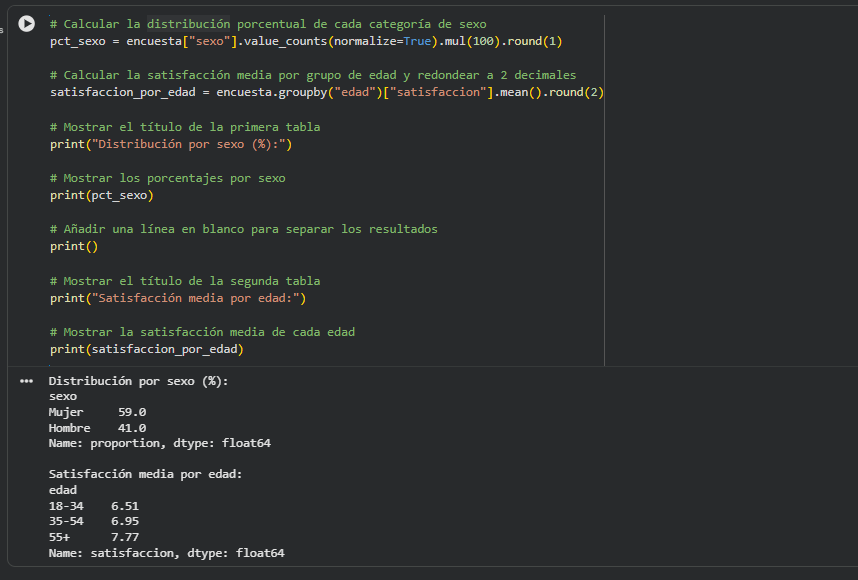
Summarise a table of 300 records: distribution by sex and average satisfaction by age group.
Method
- Define the calculation and understand the concepts
- Generate code with AI assistance
- Run it in Colab
- Review the results
- Represent them in a chart
Practice evidence
Results
Distribution by sex
Share of the 300 synthetic records.
| Group | Percentage |
|---|---|
| Women | 59 % |
| Men | 41 % |
Average satisfaction by age
Average score out of 10. It is not a percentage of people.
| Age group | Mean (out of 10) |
|---|---|
| 18–34 | 6.51 |
| 35–54 | 6.95 |
| 55+ | 7.77 |
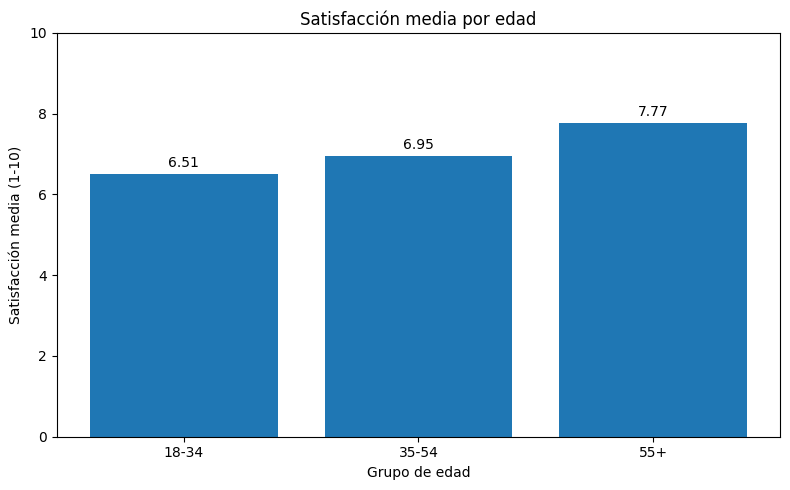
Learning exercise using 300 synthetic records. The higher satisfaction trend by age was built into the data generation. It is not a finding about real customers.
Interpretation and limits
Reading the results
I kept the indicators distinct according to what they describe: the percentage distribution shows the composition of the records, while the averages summarise ratings for each group. The chart makes them comparable on the same scale.
02 Prompt ControlHow a response changes when the way we ask changes. Open practiceClose practice
Interactive exercise using a fictional scenario.
This Prompt Control case uses a fictional situation and contains no real customer or company data.
What I want to observe
I make the same request five times, adding one more layer each time, and compare how the answer changes. The underlying idea: working well with AI isn’t about asking a question, but about preparing the brief well.
How I test it
- 1 · Just the question
- 2 · + who it’s for and why
- 3 · + tone, format and limits
- 4 · + an example of what I expect
- 5 · + “check before you answer”
- I compare the 5 answers
Step-by-step example · ChatGPT, each version in a new chat
Case: a review from Marta, a regular customer whose order arrived five days late without anyone letting her know.
Version 1
What I asked
«Responde a esta reseña.»
What it replied
«Hola Marta, sentimos mucho el retraso y, sobre todo, no haberte informado de que tu pedido llegaría más tarde de lo previsto. Entendemos tu decepción, especialmente después de tantos años confiando en nosotros. Gracias por hacérnoslo saber. Revisaremos qué ha ocurrido para evitar que vuelva a suceder y mejorar nuestra comunicación cuando haya cualquier incidencia con una entrega. Esperamos recuperar tu confianza en tu próxima experiencia con nosotros.»
Version 2
What I added
Who it’s for and why: “It’s Marta, a regular customer of an online shop. The goal is for her to feel heard and trust us again.”
What it replied
«Hola Marta, Sentimos mucho el retraso y, sobre todo, que no te avisáramos a tiempo. Entendemos perfectamente tu decepción, especialmente después de tantos años confiando en nosotros. Agradecemos que nos lo hayas contado. Vamos a revisar qué ocurrió para evitar que vuelva a pasar y mejorar la comunicación cuando haya cualquier incidencia con un pedido. Esperamos poder recuperar tu confianza en tu próxima compra.»
Version 3
What I added
Tone, format and limits: “Warm and sincere tone, no excuses or stock phrases. Four sentences at most. Don’t offer discounts.”
What it replied
«Marta, siento que tu pedido llegara cinco días tarde y que no te avisáramos. Entiendo que te haya decepcionado, sobre todo después de tantos años comprando con nosotros. Vamos a revisar qué falló en el seguimiento y en el aviso del retraso. Queremos recuperar tu confianza con una experiencia mejor.»
Version 4
What I added
An example of the style I want, taken from another case: «Javier, tienes razón: el producto no era lo que mostrábamos en la foto. Ya lo hemos corregido en la web para que no le pase a nadie más. Gracias por avisarnos con tanto detalle.»
What it replied
«Marta, tienes razón: además del retraso, deberíamos haberte avisado de que tu pedido no llegaría a tiempo. Sabemos que llevas años confiando en nosotros y entendemos que esta vez te hayamos decepcionado. Gracias por decírnoslo; revisaremos qué falló en la comunicación para evitar que vuelva a ocurrir.»
Version 5
What I added
A review before replying: “Check your draft: that it doesn’t promise anything we can’t deliver, doesn’t sound templated and addresses what bothered her most.”
What it replied
«Marta, tienes razón: lo peor no fueron solo los cinco días de retraso, sino que nadie te avisara. Después de tantos años comprando con nosotros, entendemos especialmente tu decepción. Gracias por señalarlo con tanta claridad; revisaremos cómo estamos comunicando este tipo de incidencias para evitar que vuelva a pasar.»
Each version adds one layer to the previous one.
The human role
Compares the answers and weighs which one best fits what was needed, and why.
What I learn
Context alone barely changed the reply. Defining the tone and length, and giving an example, improved it. The final review focused on what upset Marta most: no one had warned her. It still needed one last human edit.
03 Research FlowWhich parts of research can be automated while preserving interpretation. Open practiceClose practice
Conceptual proposal. Not tested yet.
What I want to observe
How far the machine can go in sorting things out, and where the work of understanding begins. A pattern is a clue, not necessarily the explanation.
How I test it
- Customer comments
- Automatic classification
- Thematic grouping
- Pattern detection
- Hypotheses
- Human review
The human role
Reviews the hypotheses, checks them against the context and decides what deserves deeper research.
What I learn
Organising information and understanding it are different jobs. Context still needs interpretation.
04 Human in the loopWhere automation fits and when a person needs to intervene. Open practiceClose practice
Conceptual proposal. Not tested yet.
What I want to observe
Which tasks can run on their own, and at what point a human review prevents costly mistakes later on.
How I test it
- Welcome
- AI processes
- Human validation
- Continue · Correct · Stop
The human role
Decides at the validation point: whether the result moves on, gets corrected or stops.
What I learn
A workflow needs review points where a person can correct it or stop it.
05 AI Quality CheckHow to avoid accepting an answer simply because it sounds confident. Open practiceClose practice
Conceptual proposal. Not tested yet.
What I want to observe
That a well-written answer is not the same as a reliable one, and which checks help tell them apart.
How I test it
- AI generates an answer
- Second review layer: sources, contradictions, errors and biases
- Confidence level
- A person decides whether it holds up
The human role
Reads the review and decides whether the answer works, needs changes or is discarded.
What I learn
The content and sources need checking, alongside how the answer is written.
06 AI vs AIWhat happens when one AI questions or checks another AI’s response. Open practiceClose practice
Conceptual proposal. Not tested yet.
What I want to observe
Whether disagreement between agents helps reveal blind spots… or just adds noise.
How I test it
- One agent proposes an interpretation
- Another agent challenges it: looks for flaws and alternative explanations
- Weighing the arguments
- The final decision is human
The human role
Listens to both agents, weighs their arguments and makes the final decision.
What I learn
Two different answers raise questions. Their disagreement does not by itself prove which is correct.
07Model ChoiceReading benchmarks with judgementWhich model should I choose for a task?Open practiceClose practice
Interactive exercise based on a fixed snapshot.
Read a benchmark snapshot, distinguish its metrics and check what we can conclude from them.
Snapshot from October 2026. It does not update in real time.
Speed measures output tokens per second. Cost per Task is the benchmark’s weighted average cost, not a guaranteed price for your own task.
Four questions to explore the snapshot. You can change your answer.
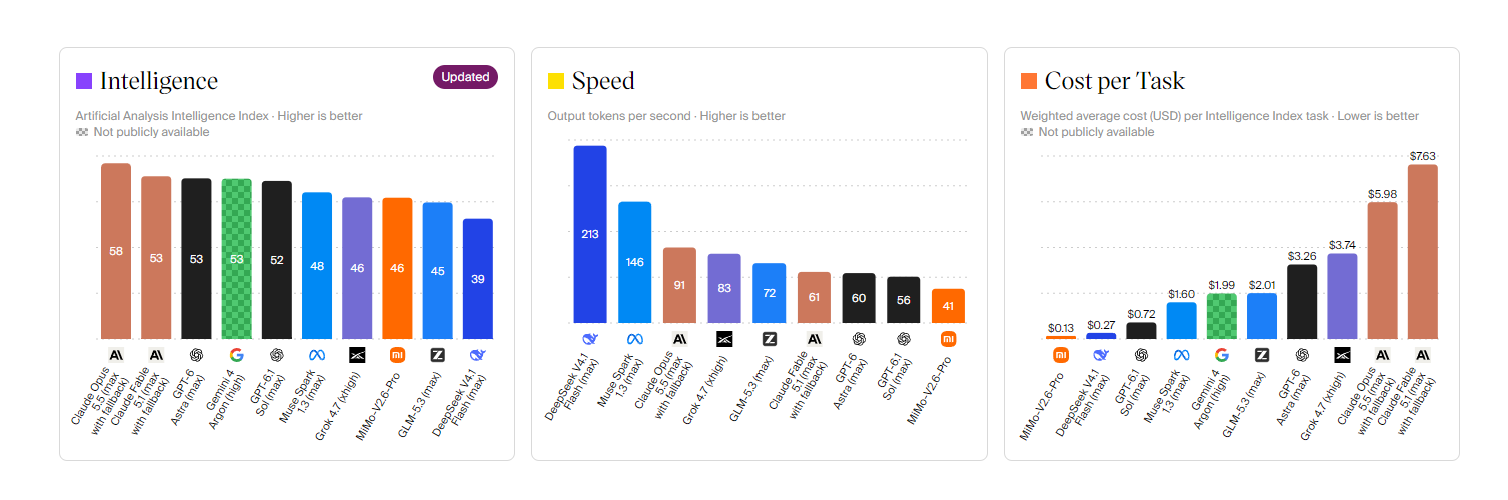
According to the snapshot, which generates the most tokens per second?
Which has the lowest Cost per Task in this snapshot?
Among these three options, which has the highest Intelligence score?
Can these charts identify the most efficient model for every task?
Faster, cheaper and more suitable are different questions. The decision starts by defining what we need to obtain.